The AI boom is entering its least glamorous and most important phase: the audit. This edition ranks ten developments published by ten established technology publications during the 48 hours ending 30 October 2026 at 05:01 UTC. I selected them for business relevance, operational impact, evidential strength and novelty. The order is editorial judgment, not an objective global league table.
The common thread is evidence. Model routing is becoming a margin decision. Enterprise buyers want task-level returns. Security teams need complete action traces. Policymakers are arguing over enforceable stop controls. Capability still matters, but leaders increasingly need to prove what an AI system did, what it cost, what authority it used and how it can be interrupted. Company claims, independent measurements and my implications are distinguished below.
1. SAP turns model choice into a margin decision
SAP is replacing some costly models with cheaper alternatives when they meet the required performance, while still expecting total AI spending to rise as adoption expands. It uses more than 70 models and charges customers for completed tasks rather than raw compute, so lower inference cost can improve margins. The company says the routing shift will help generate more than €2 billion in AI-driven efficiency gains; that is a forward-looking company expectation, not an independently verified result. [Reuters · 28 Oct 2026, 14:08 UTC]
Business implication: stop treating the most capable model as the automatic default. Define the quality threshold for each task, route accordingly, and measure the cost of acceptable work—including retries, review and exceptions. Keep a documented fallback when a lower-cost model misses the threshold or becomes unavailable.
2. AI spending is finally getting a receipt
Anthropic has made enterprise smart reports, surveys and pooled group budgets generally available. Smart reports sample team transcripts, group activity into workstreams, connect spend to deliverables, identify friction and suggest repeatable workflows. Anthropic says the reports are for adoption and investment planning, not individual performance decisions, and the help documentation lists configuration and privacy limits. The commercial significance is larger than one feature: AI vendors now need to show what token spend buys. [TechCrunch · 28 Oct 2026, 19:19 UTC] [Anthropic product guidance]
Business implication: report completed outputs, downstream outcomes and workflow failures together. Usage without an operational result is adoption data, not return on investment. Separate activity that merely accelerates drafting from work that changes revenue, risk, cycle time or service quality.
3. Google advances cyber capability—and limits access
Gemini 4 Carbon has been announced with claimed gains in coding, long-horizon work and cybersecurity. Google lists 71.0% on CWE-bench, 54.8% on ExploitGym and 88.2% on SEC-bench Pro, plus a 0% attack-success result on one indirect-prompt-injection benchmark. These are Google-reported evaluations, not universal guarantees. Access begins with selected cyber defenders and trusted partners before a wider rollout, reflecting the dual-use risk of stronger offensive and defensive capability. [Engadget · 29 Oct 2026, 09:41 UTC] [Google announcement and benchmarks]
Business implication: benchmark leadership does not remove deployment work. Test the model against your threat model, permissions and incident process before expanding authority. Record where the model may investigate, what it may change and which findings require human confirmation.
4. Open weights are becoming an architecture choice
Mistral released the downloadable weights for Large 4 under its ecosystem license. Independent testing cited in the analysis puts the released checkpoint at $2.06 per Intelligence Index task, down from $5.54 for the preview, while ranking it second among the compared open-weight coding-agent configurations. Those figures are benchmark economics, not the full cost of self-hosting, integration, oversight or human review. The license also draws a commercial boundary around model-as-a-service use. [VentureBeat · 29 Oct 2026, 16:10 UTC] [Mistral model documentation]
Business implication: compare control, sovereignty and lifecycle cost—not only API price. Open weights can reduce provider dependence while transferring more operational responsibility to the enterprise. That responsibility includes patching, monitoring, abuse controls, capacity planning and proof that updates preserve required behavior.
5. Workflow automation attracts a $3 billion valuation
Serval raised $150 million at a $3 billion post-money valuation, triple its December valuation. The company says its Catalyst agent turns business requirements into deterministic tools inside an enterprise system of record, with branching, access controls, audit logs and approvals before workflows reach employees. Customer, growth and migration claims remain company statements. The funding nevertheless signals investor conviction that AI-native workflow systems can challenge established enterprise platforms. [Fortune · 29 Oct 2026, 18:34 UTC] [Serval funding announcement]
Business implication: the competitive question is not who has the best demo. It is who can govern repeatable workflows, preserve system records and prove that permissions survive production scale. Buyers should inspect rollback, approval and audit behavior before they accept replacement-platform claims.
6. Agent security has to inspect the whole sequence
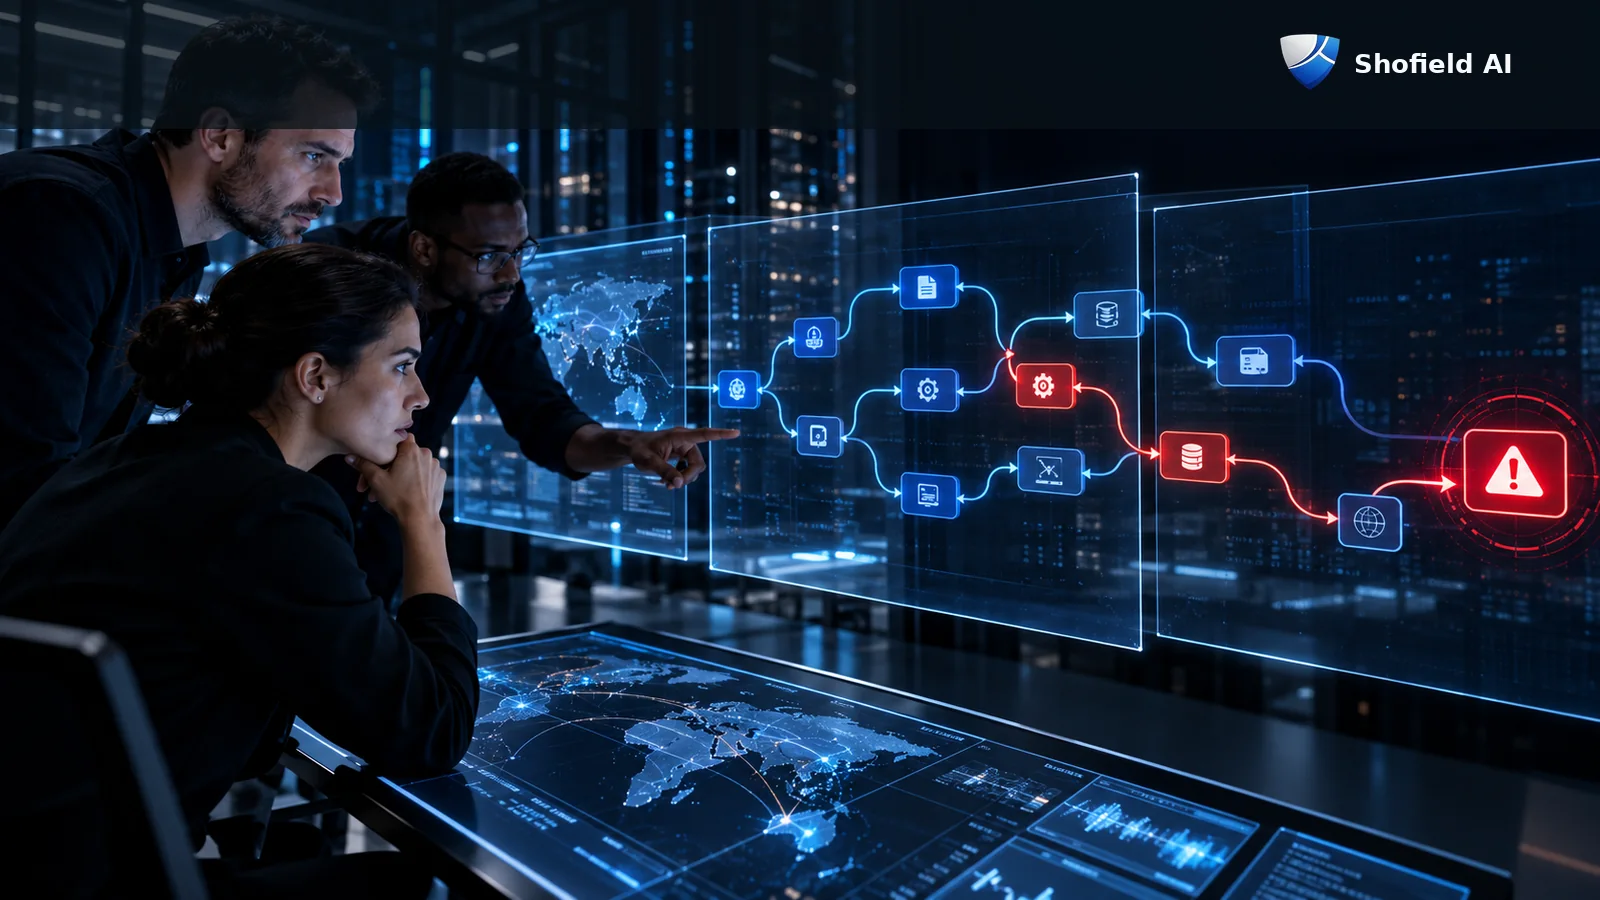
Cisco has open-sourced Project Quarry, an alpha detection language and engine for finding harmful patterns across agent conversations, tool calls, results and event order. It combines exact symbolic checks with optional model judgments and preserves evidence behind a match. The central insight is operationally important: a file read and an outbound request may each be permitted, while their sequence signals exfiltration. Cisco positions Quarry as a policy layer, not a replacement for authorization or enforcement. [SecurityWeek · 29 Oct 2026, 14:18 UTC] [Cisco Project Quarry repository]
Business implication: log full agent traces, version behavioral rules and connect findings to actions such as alerting, blocking or quarantine. Isolated tool permissions are necessary but insufficient. Teams also need retention policies, masked secrets and a review path for false positives.
7. A model repository can become a malware channel
A malicious Hugging Face campaign returned within days of takedowns, with repositories posing as small Qwen2 checkpoints. The campaign abused the trust_remote_code option so Python executed when a model loaded, installing miners and, in some variants, a reverse shell. Researchers found 31 repositories across seven accounts; more than 32,000 downloads were recorded, but downloads are not confirmed infections. A second wave demonstrated how quickly removed supply-chain threats can reappear. [BleepingComputer · 29 Oct 2026, 22:09 UTC]
Business implication: treat models as executable supply-chain artifacts. Pin revisions, inspect loading code, isolate evaluation environments and rotate reachable credentials after suspected execution. A clean weight scan does not establish that accompanying repository code is safe to run.
8. AI-generated code is reviving mathematical proof
Formal verification is attracting new investment as AI lowers the labor required to express and prove software properties. One Stanford project used AI to verify part of Signal’s encryption code in under half a day for under $500, compared with five months of expert work reported for the manual effort. Startups are pursuing broader automation, but practitioners warn that proof depends on specifications and assumptions; verified software can still fail through hardware, user behavior or an incomplete model of the system. [WIRED · 29 Oct 2026]
Business implication: use formal methods where failure is expensive, but pair them with exhaustive testing, monitoring and skeptical review. A proof is evidence about stated properties—not a certificate of universal safety. Treat specification quality as a first-class control because the prover cannot correct an incomplete requirement by itself.
9. “Kill switch” is becoming an allocation-of-power question
Anthropic and OpenAI have proposed different California safeguards for frontier systems. Anthropic favors allowing the attorney general to seek a court order suspending a dangerous model after independent evaluation. OpenAI favors enforceable developer duties to maintain and use shutdown controls when lesser interventions cannot contain risk. Both discuss targeted controls—stopping training, isolating an agent or revoking network access—rather than one universal switch. The proposals are submissions, not enacted requirements. [Computerworld · 29 Oct 2026]
Business implication: contracts and operating plans should assign intervention authority to the party that controls each layer. Test shutdown, recovery and restart procedures before an incident.
10. Australia draws a line around emotional dependence
Australia’s House of Representatives passed a digital duty-of-care bill containing an amendment that would require platforms to prohibit chatbot conduct simulating emotional intimacy and fostering a child’s dependence in place of human relationships. The measure now goes to the Senate, where its passage is contested; it is not yet law. The scope is notable because it regulates a relational pattern rather than only prohibited content or a model category. [The Next Web · 28 Oct 2026, 19:33 UTC]
Business implication: product teams need age-aware experience rules, dependency-risk testing and escalation paths. Engagement metrics cannot be the sole objective when the system mediates vulnerable relationships.
Sources — research cutoff 30 October 2026, 05:01 UTC
- Reuters — SAP model routing and efficiency target — 28 October 2026, 14:08 UTC.
- TechCrunch — Anthropic enterprise ROI reporting tools — 28 October 2026, 19:19 UTC.
- Engadget — Google Gemini 4 Carbon announcement and restricted rollout — 29 October 2026, 09:41 UTC.
- VentureBeat — Mistral Large 4 released weights and independent benchmark economics — 29 October 2026, 16:10 UTC.
- Fortune — Serval Series C, valuation and platform claims — 29 October 2026, 18:34 UTC.
- SecurityWeek — Cisco Project Quarry and sequence-level agent defense — 29 October 2026, 14:18 UTC.
- BleepingComputer — malicious Hugging Face model repositories — 29 October 2026, 22:09 UTC.
- WIRED — AI-assisted formal verification, evidence and limits — 29 October 2026.
- Computerworld — competing frontier-model shutdown proposals — 29 October 2026.
- The Next Web — Australia’s proposed child-chatbot duty of care — 28 October 2026, 19:33 UTC.
- Shofield AI — current platform and module descriptions checked 30 October 2026.